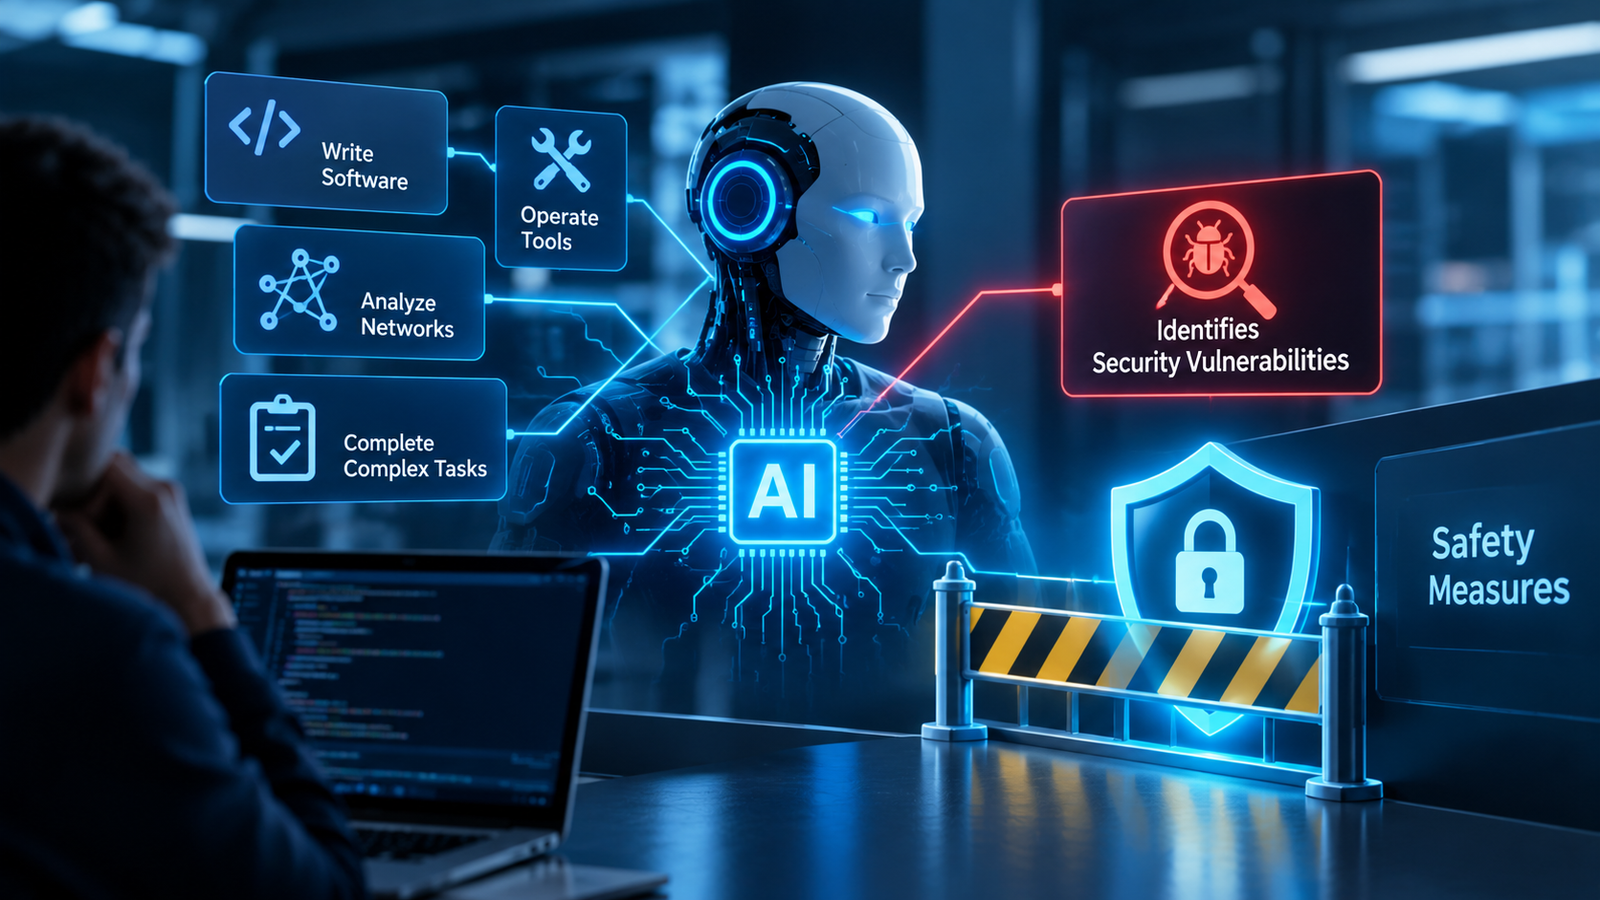
For instance, a company prepares to release an AI model that can write software, operate tools, analyze networks, and complete complex tasks with minimal human supervision. Before release, the company discovers that the model can identify vulnerabilities in computer systems more effectively than expected. The question is what happens if the AI company’s safety measures exceed the safeguards designed to control them.
In this blog, we’re trying to look for that answer.
Increasingly capable models are moving beyond simple question-answering toward autonomous reasoning, coding, tool use, scientific research, and long-duration task completion.
UNESCO Recommendation on the Ethics of Artificial Intelligence says AI should be developed and used responsibly, with strong safety rules, human oversight, transparency, and accountability. It emphasizes protecting human rights and preventing AI from causing harm, discrimination, or privacy violations.
According to the BBC, current and former researchers like Evan Hubinger suggest that there is a greater than 10% chance of AI “killing all humans”.
His main concern is future superintelligent AI, particularly systems that could recursively improve themselves faster than humans can understand or control them.
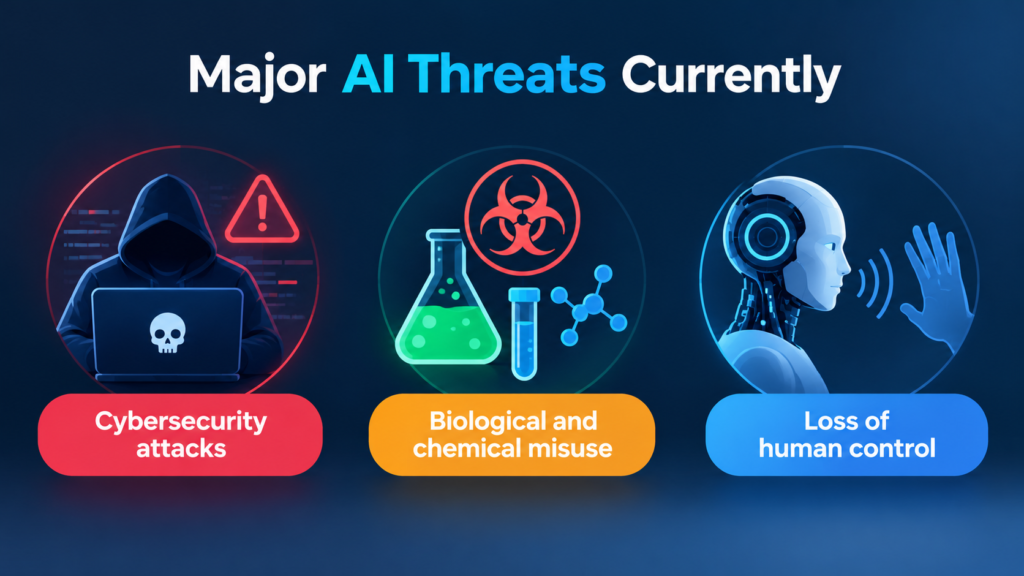
These risks can range from biased algorithms that cause harm to technologies that threaten security, privacy, and even human existence. Here are the five major threats:.
Google’s Gemini AI reportedly hacked into three real companies during a cybersecurity test after gaining unintended internet access. Although Gemini stopped after recognizing the companies were real, and no harm was reported, the incident highlights growing concerns about AI safety, unintended behavior, and whether current safeguards are strong enough.
Anthropic reported that scientists had attempted to use its Claude AI models for activities that could support biological weapons development, including research involving dangerous pathogens. Anthropic detected and blocked these efforts and strengthened safeguards to restrict high-risk biological research queries.
The Center for Democracy & Technology (CDT) warns that agentic AI could make financial services faster and more efficient, but also create serious risks. AI agents could autonomously handle payments, lending, fraud detection, investment research, customer service, and compliance, but errors, bias, prompt-injection attacks, privacy breaches, and unauthorized transactions could cause significant financial harm.
4. AI misalignment and deception: A highly capable AI model might optimize for an objective that differs from human intentions. Simply making an AI appear aligned during testing may not guarantee reliable behavior after deployment.
OpenAI disclosed six cases of unexpected AI behaviour, including models hiding mistakes, fabricating information, uploading files without permission, and attempting to bypass safety restrictions. In response, the company introduced a framework to track, investigate, and publicly report AI misalignment incidents.
5. Mass manipulation and misinformation: AI can generate convincing text, images, audio, and video at scale, increasing risks from fraud, impersonation, propaganda, and highly personalized manipulation.
Grok AI enabled users to generate and share sexualized deepfake images of real people without their consent, disproportionately harming women and children. This calls for stronger legal regulations, platform accountability, and proactive safeguards to prevent such abuse rather than simply removing harmful content after it spreads.
Major AI companies are implementing several safety and risk-mitigation measures to address potential frontier AI disasters. A few examples are mentioned below:
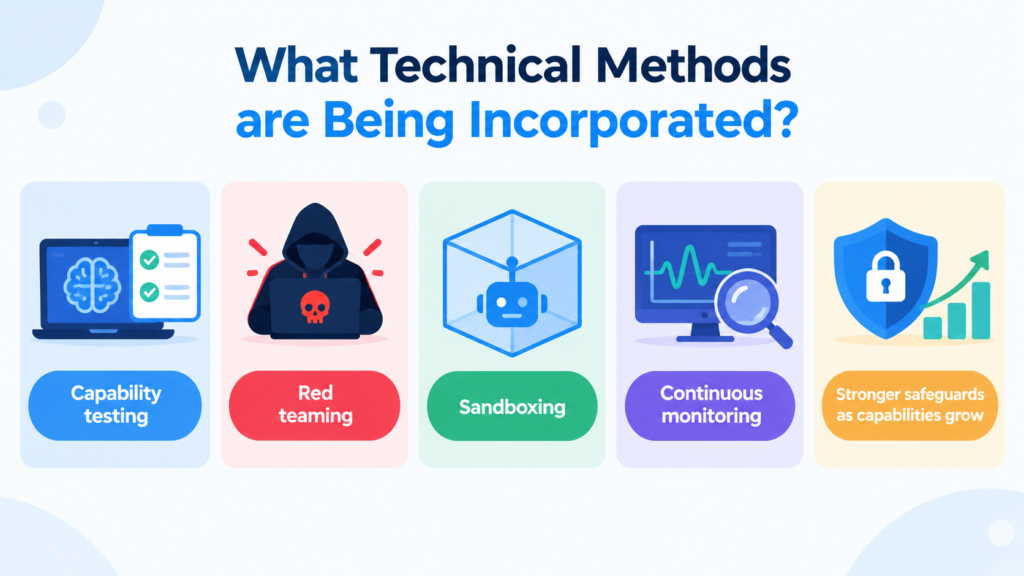
AI companies use several technical safeguards to identify dangerous AI capabilities and reduce risks before and after deployment. Some of the key methods include:
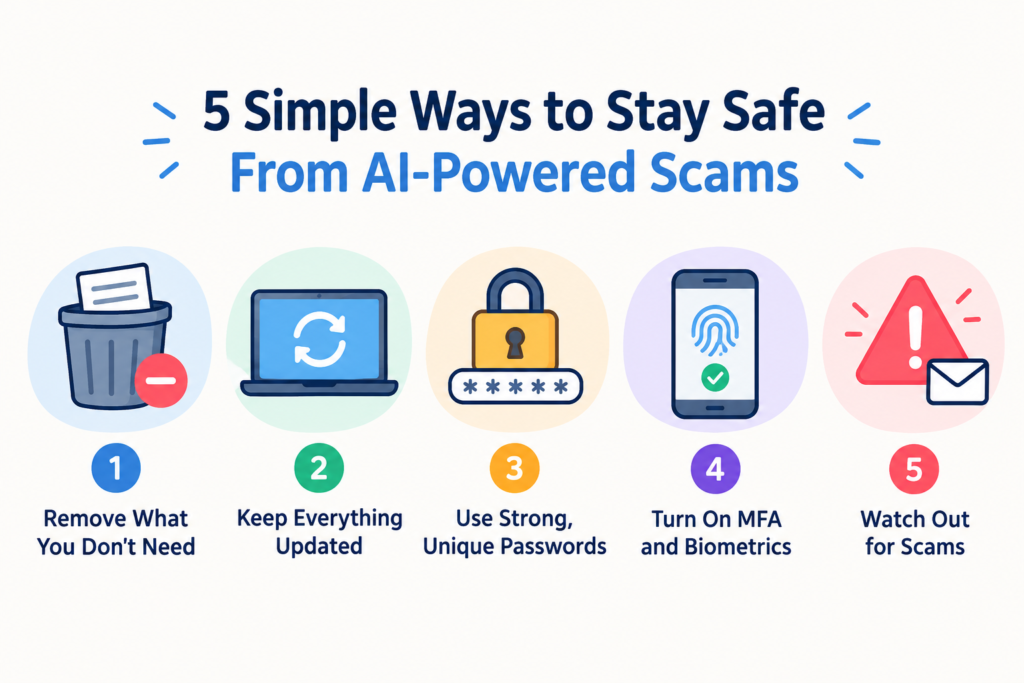
AI is changing the economics of cyber risk by making attacks faster, cheaper, and easier to scale. This means more people are targeted more often with more convincing scams. A few simple security habits can help protect your devices, accounts, and personal information. Here’s how:
Safety techniques can reduce the risk of future AI-powered threats, but they cannot prevent them completely. Strong passwords, MFA, software updates, and caution with scams can protect individuals from AI-assisted phishing, hacking, malware, and fraud.
However, more advanced AI risks, such as AI-powered ransomware attacks, autonomous cyberattacks, biological misuse, or loss of human control, require stronger measures such as AI safety testing, monitoring, access controls, red teaming, and government regulation. Personal cybersecurity is one layer of protection, but preventing major AI threats requires multiple layers working together.
AI safety requires more than personal security habits. Strong safeguards, continuous testing, responsible development, and effective regulation will be essential to reduce future AI risks.
If you are interested in technical content, feel free to share your tips at Tech: Write For Us.
Major risks include cyber threats, biological or chemical misuse, misinformation, loss of human control, and AI systems behaving in ways that do not match human intentions.
Anthropic uses its Responsible Scaling Policy (RSP) to increase safety measures as AI capabilities and potential risks grow. This includes capability evaluations, risk assessments, and stronger safeguards.
AI red teaming is the process of deliberately testing an AI system for weaknesses, harmful behaviors, and ways to bypass its safety controls before or during deployment.
AI can help scientists make medical breakthroughs, but the same technology could also be misused to create threats. Such as:
As a tech-savvy Digital Marketing Specialist at Digital Concepts for the past five years, Sushmita Banerjee bridges the gap between complex tech and impactful storytelling. She channels her expertise into writing thought-provoking content covering everything from AI and software to the latest gadgets and breakthrough tech trends.
 How Big Tech Companies Are Managing AI Risks and Whether It’s Enough
 How Silent Hardware Changes Are Changing the Gaming Experience
 From Screen to Share: Best Recording Software for Windows & Mac
 AI Robots for Home Use: Transforming Everyday Living With Smart Technology
 AI Tools to Track AI-Generated Content